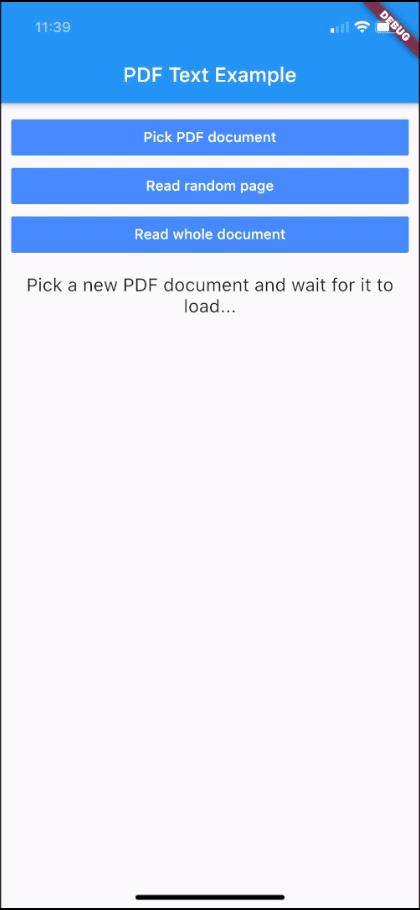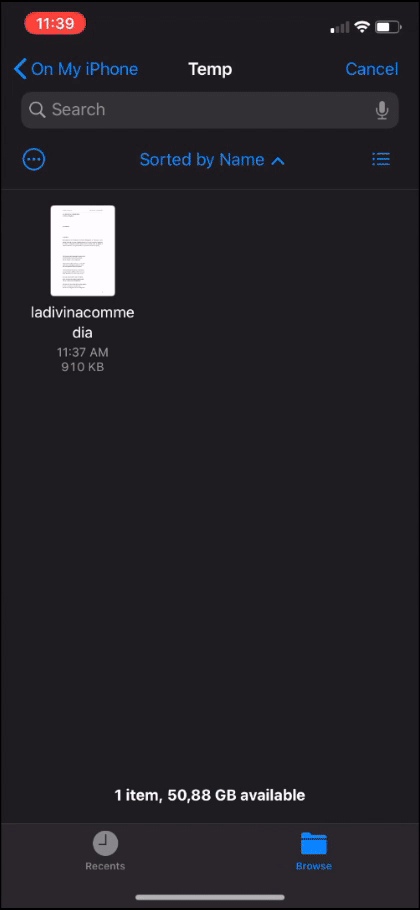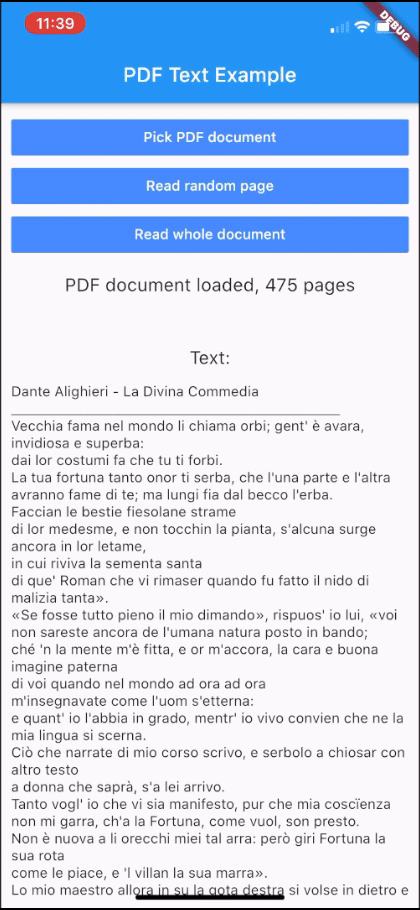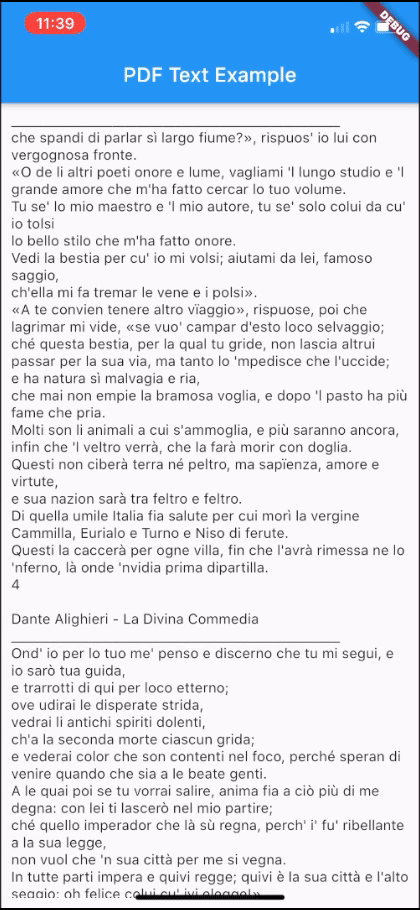
pdf_text 패키지는 Android 및 iOS에서 PDF 문서의 텍스트 콘텐츠를 읽고 추출할 수 있도록 해주는 플러터 플러그인입니다. PDF 페이지를 읽을 수 있는 문자열로 변환하여 플러터 앱 내에서 PDF 텍스트를 처리하거나 표시하는 것을 쉽게 만듭니다. 간단함과 크로스플랫폼 호환성을 고려해 설계되었으며, 기존 플러터 프로젝트에 원활하게 통합됩니다. 전체 PDF 렌더링 없이 텍스트 추출이 필요한 애플리케이션에 이상적입니다.
사용 사례
스캔된 PDF에서 텍스트 추출
문서 검색 기능 구축
앱에서 텍스트 미리보기 만들기
분석을 위한 PDF 콘텐츠 파싱
접근성 기능 지원
주요 기능
크로스 플랫폼 지원 (iOS 및 안드로이드)
간단한 텍스트 추출 API
가볍고 빠름
완전한 PDF 렌더링이 필요하지 않습니다
스캔 및 입력된 PDF와 호환됩니다
적합한 대상
문서 처리 앱
교육 도구
콘텐츠 인덱싱 시스템
접근성 향상
텍스트 기반 검색 구현
고려 사항
텍스트 추출에 제한됨(서식 없음)
고도로 스캔되거나 저품질의 PDF 파일을 처리하는 데 어려움을 겪을 수 있습니다
암호화된 PDF를 지원하지 않습니다
PDF에 대해 파일 경로 입력이 필요합니다
성능은 PDF 크기와 복잡성에 따라 달라집니다
원본 README
연결된 소스 저장소의 README 원문 스냅샷입니다. 최신 내용은 저장소에서 확인하세요.
PDF Text Plugin
This plugin for Flutter allows you to read the text content of PDF documents and convert it into strings. It works on iOS and Android. On iOS it uses Apple's PDFKit. On Android it uses Apache's PdfBox Android porting.
Getting Started
Add this to your package's pubspec.yaml file:
dependencies:pdf_text:^0.5.0
Usage
Import the package with:
import'package:pdf_text/pdf_text.dart';
Create a PDF document instance using a File object:
Optionally, you can delete the file of a document when you no longer need it.
This can be useful when you import a PDF document from outside the local
file system (e.g using a URL), since it is automatically stored in the temporary
directory of the app.
Delete the file of a single document:
doc.deleteFile();
or delete all the files of all the documents imported from outside the local
file system:
PDFDoc.deleteAllExternalFiles();
Functioning
This plugin applies lazy loading for the text contents of the pages. The text is cached page per page. When you request the text of a page for the first time, it is parsed and stored in memory, so that the second access will be faster. Anyway, the text of pages that are not requested is not loaded. This mechanism
allows you not to waste time loading text that you will probably not use. When you request the text content of the entire document, only the pages that have not been loaded yet are then loaded.
Public Methods
PDFDoc
Return
Description
PDFPage
pageAt(int pageNumber) Gets the page of the document at the given page number.
static Future<PDFDoc>
fromFile(File file, {String password = ""}) Creates a PDFDoc object with a File instance. Optionally, takes a password for encrypted PDF documents.
static Future<PDFDoc>
fromPath(String path, {String password = ""}) Creates a PDFDoc object with a file path. Optionally, takes a password for encrypted PDF documents.
static Future<PDFDoc>
fromURL(String url, {String password = ""}) Creates a PDFDoc object with a url. Optionally, takes a password for encrypted PDF documents.
void
deleteFile() Deletes the file related to this PDFDoc. Throws an exception if the FileSystemEntity cannot be deleted.
static Future
deleteAllExternalFiles() Deletes all the files of the documents that have been imported from outside the local file system (e.g. using fromURL).
Objects
classPDFDoc{
int length; // Number of pages of the documentList<PDFPage> pages; // Pages of the documentPDFDocInfo info; // Info of the documentFuture<String> text; // Text of the document
}
classPDFPage{
int number; // Number of the page in the documentFuture<String> text; // Text of the page
}
classPDFDocInfo{
String author; // Author string of the documentList<String> authors; // Authors of the documentDateTime creationDate; // Creation date of the documentDateTime modificationDate; // Modification date of the documentString creator; // Creator of the documentString producer; // Producer of the documentList<String> keywords; // Keywords of the documentString title; // Title of the documentString subject; // Subject of the document
}
Contribute
If you have any suggestions, improvements or issues, feel free to contribute to this project.
You can either submit a new issue or propose a pull request. Direct your pull requests into the dev branch.