सार्वजनिक जानकारी से बना चयन मार्गदर्शन। केवल संदर्भ हेतु।
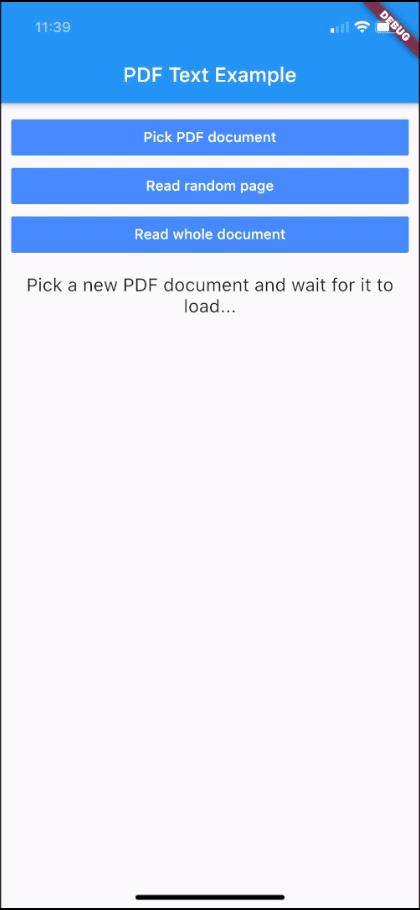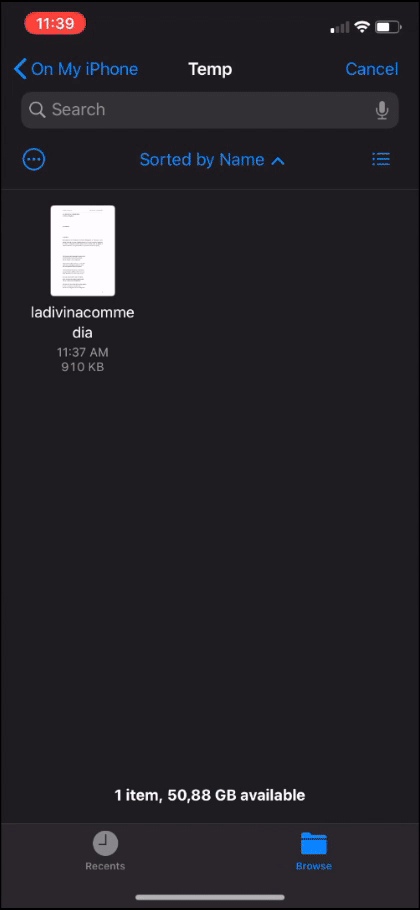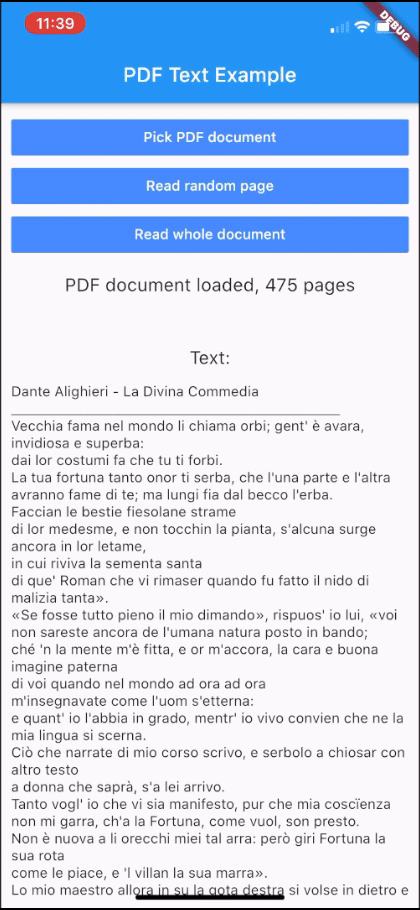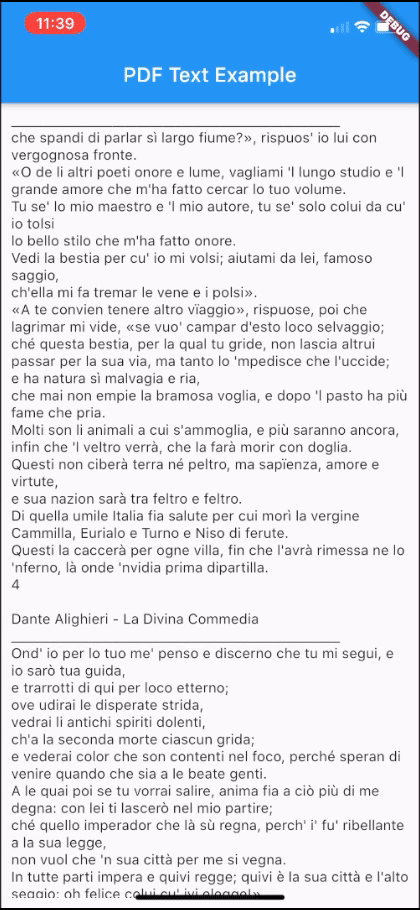
pdf_text पैकेज एक फ्लटर प्लगइन है जो एंड्रॉइड और आईओएस पर PDF दस्तावेज़ से टेक्स्ट कंटेंट पढ़ने और निकालने की अनुमति देता है। यह PDF पेज को पढ़ने योग्य स्ट्रिंग में बदलता है, जिससे फ्लटर ऐप्स में PDF से टेक्स्ट को प्रोसेस या दिखाना आसान हो जाता है। सरलता और क्रॉस-प्लेटफॉर्म संगतता के लिए डिज़ाइन किया गया, यह मौजूदा फ्लटर प्रोजेक्ट्स में आसानी से एम्बेड किया जा सकता है। इस पैकेज का उपयोग पूरी PDF रेंडरिंग के बिना टेक्स्ट निकालने की आवश्यकता वाले ऐप्स के लिए आदर्श है।
उपयोग
स्कैन किए गए PDF से पाठ निकालना
दस्तावेज़ खोज सुविधाएं बनाना
एप्स में पाठ पूर्वावलोकन बनाना
विश्लेषण के लिए PDF सामग्री का विश्लेषण करना
प्रवेश विशेषताओं का समर्थन करना
मुख्य विशेषताएँ
क्रॉस-प्लेटफॉर्म समर्थन (iOS और Android)
सरल पाठ निकालने एपीआई
हल्का और तेज़
पूर्ण PDF प्रदर्शन की आवश्यकता नहीं है
स्कैन और टाइप किए गए PDFs के साथ काम करता है
इनके लिए उपयुक्त
दस्तावेज़ प्रोसेसिंग ऐप्स
शैक्षिक उपकरण
सामग्री इंडेक्सिंग प्रणाली
प्राप्ति सुधार
पाठ-आधारित खोज कार्यान्वयन
विचार योग्य बातें
पाठ निकालने पर सीमित (बिना प्रारूपण के)
भारी रूप से स्कैन किए गए या कम गुणवत्ता वाले PDFs के साथ कठिनाइयों का सामना कर सकते हैं
एन्क्रिप्टेड PDFs का समर्थन नहीं करता है
PDF के लिए फ़ाइल पथ इनपुट की आवश्यकता होती है
प्रदर्शन PDF के आकार और जटिलता पर निर्भर करता है
मूल README
संबंधित सोर्स रिपॉज़िटरी के मूल README का स्नैपशॉट। नवीनतम सामग्री के लिए रिपॉज़िटरी देखें।
PDF Text Plugin
This plugin for Flutter allows you to read the text content of PDF documents and convert it into strings. It works on iOS and Android. On iOS it uses Apple's PDFKit. On Android it uses Apache's PdfBox Android porting.
Getting Started
Add this to your package's pubspec.yaml file:
dependencies:pdf_text:^0.5.0
Usage
Import the package with:
import'package:pdf_text/pdf_text.dart';
Create a PDF document instance using a File object:
Optionally, you can delete the file of a document when you no longer need it.
This can be useful when you import a PDF document from outside the local
file system (e.g using a URL), since it is automatically stored in the temporary
directory of the app.
Delete the file of a single document:
doc.deleteFile();
or delete all the files of all the documents imported from outside the local
file system:
PDFDoc.deleteAllExternalFiles();
Functioning
This plugin applies lazy loading for the text contents of the pages. The text is cached page per page. When you request the text of a page for the first time, it is parsed and stored in memory, so that the second access will be faster. Anyway, the text of pages that are not requested is not loaded. This mechanism
allows you not to waste time loading text that you will probably not use. When you request the text content of the entire document, only the pages that have not been loaded yet are then loaded.
Public Methods
PDFDoc
Return
Description
PDFPage
pageAt(int pageNumber) Gets the page of the document at the given page number.
static Future<PDFDoc>
fromFile(File file, {String password = ""}) Creates a PDFDoc object with a File instance. Optionally, takes a password for encrypted PDF documents.
static Future<PDFDoc>
fromPath(String path, {String password = ""}) Creates a PDFDoc object with a file path. Optionally, takes a password for encrypted PDF documents.
static Future<PDFDoc>
fromURL(String url, {String password = ""}) Creates a PDFDoc object with a url. Optionally, takes a password for encrypted PDF documents.
void
deleteFile() Deletes the file related to this PDFDoc. Throws an exception if the FileSystemEntity cannot be deleted.
static Future
deleteAllExternalFiles() Deletes all the files of the documents that have been imported from outside the local file system (e.g. using fromURL).
Objects
classPDFDoc{
int length; // Number of pages of the documentList<PDFPage> pages; // Pages of the documentPDFDocInfo info; // Info of the documentFuture<String> text; // Text of the document
}
classPDFPage{
int number; // Number of the page in the documentFuture<String> text; // Text of the page
}
classPDFDocInfo{
String author; // Author string of the documentList<String> authors; // Authors of the documentDateTime creationDate; // Creation date of the documentDateTime modificationDate; // Modification date of the documentString creator; // Creator of the documentString producer; // Producer of the documentList<String> keywords; // Keywords of the documentString title; // Title of the documentString subject; // Subject of the document
}
Contribute
If you have any suggestions, improvements or issues, feel free to contribute to this project.
You can either submit a new issue or propose a pull request. Direct your pull requests into the dev branch.